"Which is the best observability system?" It’s a question that crops up on observability and SRE forums with clockwork regularity. As often, the best answer is “it depends”. The observability market is full of great products, just like London is full of great restaurants. Asking which one is the best is not really that meaningful. It all depends on your needs, your tastes, your appetite and your wallet.
However, even if you do meet your perfect observability match, that is not the end of the story. It is just the beginning, and, like any relationship, it is something you need to work at. Observability is business-critical. It belongs in the same tier as your CRM, your finance platform and your customer support desk. None of these just works out of the box. Each rollout is a serious project that needs specialists who understand your business processes as well as the software.
Observability is no different. A "good" system is the starting point for good outcomes, not a guarantee. Enterprise software has a well-worn cycle of disillusionment. Management buy a shiny new system and expect it to solve every problem, without investing in training or shaping it around how the organisation actually works. The ROI never materialises, management conclude they need a new system. Rinse and repeat.
Observability systems are not a magic wand. They don't plug and play - even the ones that require zero instrumentation. A technology such as eBPF gives you remarkable visibility into the kernel and the network, but it knows nothing about your business logic. You need to do all the wiring to get the right data into the system. You also need quality and volume controls for your telemetry. Otherwise you will be firehosing terabytes of debug logs or redundant Kubernetes metrics into your observability system.
No vendor can write your strategy for you, and few will try without a hefty consultancy fee attached. Before procuring a system you need to define an observability strategy to guide you through the maze. That strategy runs along two axes: resource constraints and technical requirements. Let’s examine them.
This is obviously a highly important consideration but the cheapest system is not necessarily the best option in the long run. If the user experience doesn't suit your teams, adoption will stall, and the money you saved buys a tool nobody opens. Vendor costs are not always transparent and there can be significant gotchas hidden in the small print. There are third-party brokers who will haggle with vendors on your behalf, but they take their cut, and a lower price sometimes just buys a stripped-down product.
Onboarding and trials are slow. You may shortlist half a dozen vendors, but trialling even one eats calendar time, along with the up-front effort of installation and instrumentation.
Who will administer the system and look after users and security? Who answers the alerts? Who builds the dashboards, keeps it running and watches the bill?
What problems are you trying to solve, and where does it hurt today? How will you evaluate the system and measure ROI? For some companies, observability is merely a cost centre, for others it is an investment and an accelerator. Without clear expected outcomes, you have no yardstick for the system's value.
Observability platforms have now outgrown their APM roots. Depending on your business, you may need to weigh support for:
One way or another, most vendors will tailor pricing around the volume of telemetry they ingest. How many GB of logs and traces do your systems generate each month? How many active metric series do they emit? Few teams can answer off the top of their heads, but you'll want those numbers in your pocket before you go shopping for a new stack.
Will your vendor enable you to export data to third party systems – e.g. for SIEM, Incident Management, auditing or offline analysis? How good is the API? Does it expose every feature you'll need, or only a subset? Are there quotas or rate limits on what you can pull out?
Many vendors will offer a default retention period of 30 or 60 days for your telemetry. Longer term retention periods can seriously bump up your observability bill. Some vendors' terms allow them to feed your telemetry into their machine-learning models. That may be unwelcome, and it could put you in breach of your statutory obligations or security policy. Make sure you read the small print. And if you ever leave, how easily can you take your historical data with you?
Can you bring your own storage? This is closely entwined with the sovereignty issues above but for many companies – especially those operating at very large volumes, it is also a critical factor in managing cost.
That list is far from exhaustive. You will have practical, technical and organisational questions of your own to add.
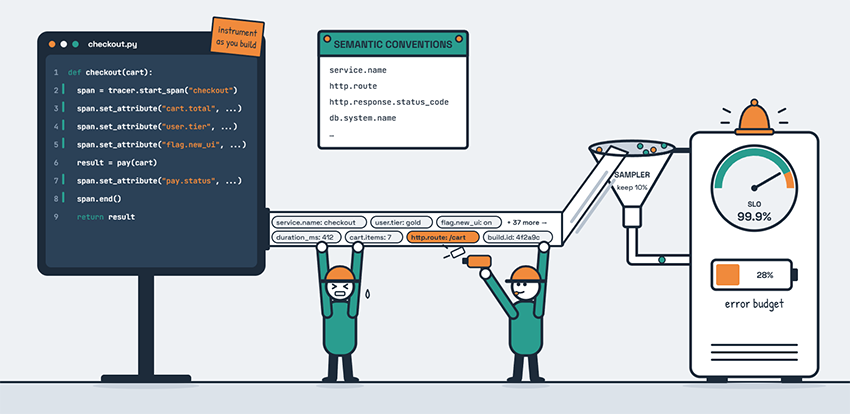
Software systems are unique combinations of code with millions of potential execution paths. The scope for logical errors is vast. Whilst many of those error conditions may be predictable, there are also plenty of unknowns and unknown unknowns. Your best defence is instrumentation that leaves a forensic trail for investigating future incidents.
Even the smartest AI cannot inject context and business-aware instrumentation into your codebase for you. It’s a process that involves input from professionals who understand your systems. Getting good telemetry out of your system also involves trudging through some pretty unglamorous groundwork, such as agreeing semantic conventions and telemetry standards. Instrumentation is a topic that could easily take up a whole book. We will just briefly cover four aspects:
Observability-driven development (ODD) represents a shift in how engineering teams approach writing, testing, and shipping software. Instead of bolting instrumentation on afterwards, or tossing it over the wall to the SREs, ODD shifts it left into the earliest stages of development. This means examining code, evaluating how it may fail in production and then enriching your telemetry with the context that you will need for effective debugging.
Arbitrarily Wide Structured Events are an approach that has been energetically championed by Honeycomb. The idea is that telemetry should encapsulate a meaningful unit of work and that you should provide as much context as possible – so that an event may contain hundreds of key value pairs. Crafting these events is not technically difficult but it does require an up front investment of time and effort (plus a backend that can cope with the cardinality).
Your observability system needs to align with the priorities and KPIs of your business. Large modern systems can run to thousands of nodes and endpoints. When the alerts start firing, you need to know which ones actually matter to your customers. Generally, this will mean defining SLOs and SLIs. The value of knowing that a CPU is running hot or that http 500 errors are up depends on their impact on the business. Some stacks support SLOs natively. Others leave you to roll your own from scripts, queries and alerts.
With an observability platform, the licence is only part of the cost. Ingestion and storage make up the rest, and both can be volatile. There are, however, levers you can pull to smooth out spikes and rein in volume. Telemetry pipelines have become a fixture of observability architectures. As well as transforming and filtering data, they can route lower-value telemetry to cheaper storage tiers. You don't have to throw more technology at the problem, though. Plain housekeeping works too: drop redundant logs and unused metrics and sample your traces.
An observability platform provides the data engine, but internal culture, engineering skill, and business context provide the steering wheel. Organisations that take a strategic view, invest in their teams and align telemetry with business outcomes will get the most out of their platforms. They will achieve greater ROI, better system performance and faster incident resolution regardless of which underlying product they choose. Most importantly, without an observability strategy, your procurement process is just a lucky dip.
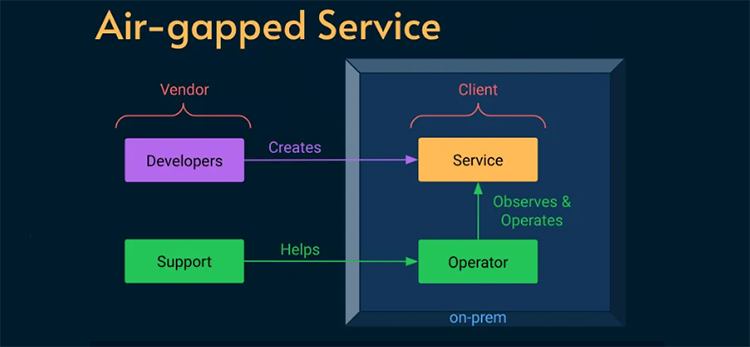
The excellent Alex Ewerlöf blog is now back in full swing and in this latest article he turns his attention to dealing with a real SRE curveball - how to build reliability engineering for an air-gapped system. We are talking hermetically sealed - not even a maintenance window for external connectivity. This task involved a high-security military facility where installing updates meant physically handing over an archive file to a system operator.
The constraints were pretty stringent - no logs, no metrics, no traces, no remote access of any kind.This was an extreme case and, ultimately, the solutions had to be both human-centred as well as relatively low-tech. How would you address the challenge? Hit the link below to read about the solution that Alex put in place.
In the past month or so the GitHub platform suffered a number of well-documented outages which resulted in loss of service for users. In the spirit of transparency, GitHub CTO Vlad Fedorov published this article on the GitHub blog, explaining the causes of the outages and the lessons learned as well as detailing the remediations that GitHub engineers will be putting in place.
The article really brings home the challenges of orchestrating the components of a global technology infrastructure - as well as the compounding effects of working at very large scale. The investigation revealed a perfect storm of edge cases, hidden tipping points and unforeseen knock-on effects. It’s impossible not to feel for the engineers sweating in the war-rooms as the dramas unfolded - after all, watching your failover fail must be pretty gut-wrenching.
If the Observability world had a code of secrecy akin to that of the Magic Circle, then Charity Majors might be in danger of being banished to exile and ignominy. In a single slide deck, she has blown the gaff on a whole trove of insider knowledge. It is the “What they don’t teach you at Harvard Business School” of observability knowledge. Not the abstract theory or technical detail but lessons and insights from the o11y frontline.
The deck in question was used in a talk at the LeadDev event in Berlin earlier this month and its 52 slides are an illuminating distillation of observability wisdom. We actually weren’t present at the talk and only came across the deck thanks to a mention in Michael Hausenblas’s excellent olly news newsletter. However, the slides contain sufficient clues (and images of unicorns) to easily re-construct the narrative and win friends and influence people as an observability savant.
If you are an SRE, when an outage happens you will know about it pretty quick. With security breaches the picture is rather less clear as, by their nature, they are designed to go undetected. Intrusion detection therefore is often based on a mixture of tools designed to spot unusual spikes, suspicious patterns or failed logon attempts.
This article by Fatih Koç argues that one of the major difficulties involved in identifying attacks is that of correlating signals across multiple sources such as Falco, Prometheus, Kubernetes Audit Logs etc. In this article, he outlines a strategy for extracting relevant data from each of these sources and pulling it together into a single observability dashboard.
The first line of cyber defence is normally at the perimeter - preventing attackers from entering your network in the first place. The next line of defence is intrusion detection. This can often take the form of anomaly detection using a variety of heuristics.
There are also some more creative possibilities, such as the canary solution adopted by Grafana. Just as the canary in the coalmine sings to alert underground workers to the presence of toxic gases, Grafana’s canary was designed to alert them to the possible presence of intruders in their domain.
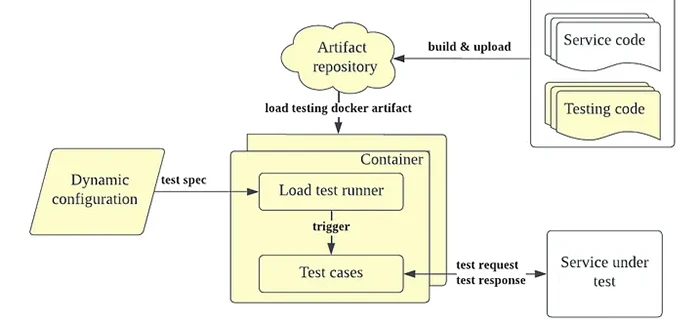
Load testing can be simple in theory but in modern distributed architectures, it involves a lot more than throwing requests at an individual service. This article on the Airbnb engineering blog looks at how the company’s engineers use the Impulse load-testing framework to handle a number of more complex requirements such as dependency mockingand managing messaging and asyncronous calls.
Unfortunately, at the moment Impulse is just an internal Airbnb framework, so you won’t be able to get your hands on it at present. At the same time, the article provides a valuable blueprint for tackling advanced, real world load testing scenarios.
It's an announcement that might have seemed unthinkable not long ago, but the porting of the revolutionary eBPF technology to Windows is now a reality. The ability to bring safe programmability to the kernel has resulted in enormous gains in fields such as security, networking and observability for Linux hosts, so applying the same principle to the Windows ecosystem is obviously an attractive proposition. It is not, though, without its own difficulties. There were a lot of hurdles to overcome and, inevitably, given the differences in OS architecture, this is not a full-fidelity replica of the Linux implementation.
This possibly foundational article by Pavel Yosifovich guides you through the steps involved in boldly going where few have gone before and creating your first eBPF program for Windows. One paragraph in the article begins with the sentence “this is where things get a bit hairy“ - for some that will likely be a challenge rather than a deterrent. This may not be cooking up nuclear fusion in your bedroom, but it does feel pretty radical.
As well as rolling out their Open AI observability solution, Elastic have also been very active within the OpenTelemetry project. C++ has a reputation for being something of a fearsome foe for observability practitioners. In this article on the Elastic blog, Haidar Braimaanie dons his protective gear and attempts to tame the beast with a soothing dose of OpenTelemetry instrumentation.
Unlike languages built in frameworks such as .NET, C++ does not have a standardized runtime environment that supports dynamic instrumentation across all platforms and compilers. C++ also uses a variety of build systems such as Makefiles and CMake, so that implementing instrumentation can be difficult and error-prone. In the article, Haidar looks at adding OpenTelemetry support to a C++ application running on Ubuntu 22.04. He also includes sample code for instrumenting the project with database spans and then observing the application in APM.
After reading this article you may want to give the C++ developer in your life a hug.
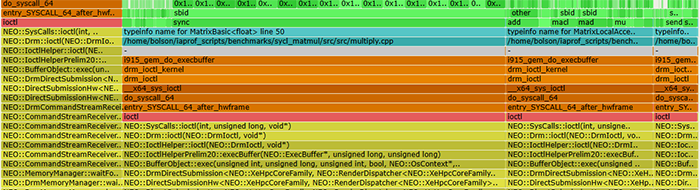
Even if you are not familiar with the name of Brendan Gregg, you are almost certainly familiar with the fruits of his labours. Brendan is the creator of the Flame Graph - one of the most important and iconic visualisations in the observability toolkit.
We featured the Flame Graph in our recent tribute to the work of UX designers in the observability arena - but you should also visit Brendans’ web site.
Brendan's latest innovation is the AI Flame Chart. This is an evolution of the original flame graph and its ambitious aim is to help reduce the vast financial and environmental costs entailed in the use of LLM’s. This means that whereas the original flame graph was focused on CPU cycles, the latest generation sets its sights on reducing GPU load. The article discusses the considerable complexities involved in mapping GPU programs back to their corresponding CPU stacks.
The names of some of the instruction sets look intimidating to the uninitiated but the basic concept of the graph is quite simple - the wider the bar, the more resource it consumes.
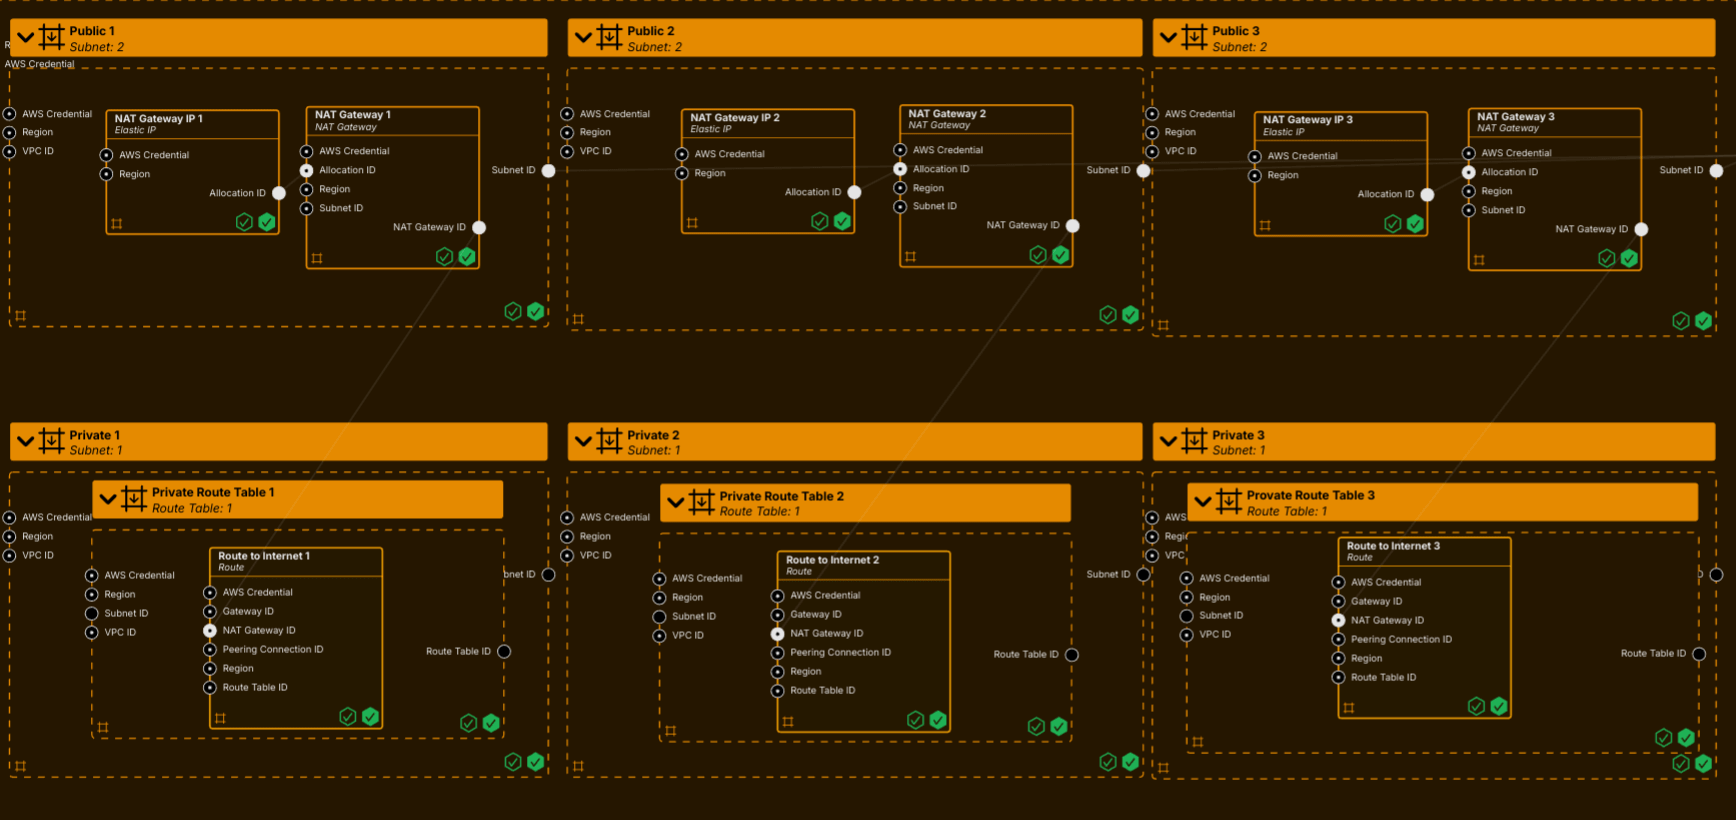
If you have ever had to grapple with a 3,000 line Helm chart to deploy your observability infrastructure, you may be forgiven for thinking that there must be a better way to do this. Whilst YAML has a certain formal elegance, its syntax struggles to express the architectures and relationships embedded in highly complex systems.
Whilst Pulumi have tackled this problem by enabling the use of high level programming languages for IaC, System Initiative are taking a fundamentally more radical approach. Their goal is nothing other than completely reinventing IaC from the ground up. The blog article for the launch of the product is an incredibly ambitious statement of intent. The terms ‘game changer’ and ‘paradigm shift’ tend to be thrown around somewhat casually, this might be a case where their usage is appropriate.
So, what are they proposing? Well, System Initiative is IaC without the code. It is a kind of digital canvas where you manipulate digital twins of your systems. Is the future here or is this the Platform Engineering equivalent of science fiction? Read the article and decide for yourself!